31 May 2011

Decimation of children.

The number of children I have is drastically reducing....
I now only have 11.76 TB of unique data including myself ( 84996 unique files in 334 datasets).
In total their are only 732 datasets now.
The number of replicas is dramatically reducing, but some children are still popular.
# Reps |# Datasets
1 |236
2 | 38
3 | 10
4 | 24
5 | 5
6 | 6
7 | 3
8 | 1
9 | 1
10 | 2
12 | 1
16 | 1
20 | 1
22 | 1
24 | 1
26 | 1
27 | 1
28 | 1
IE now only 98/334 actually have replicas.

My birthday calendar has also changed.The new birthday calendar looks like:

This shows that other than the datasets produced with in the first 12 weeks of life; at least 659 out of 718 datasets from the last year have had all copies deleted. Also show that there has been a hive of activity and new datasets produced ( a re-processing) in time for the important "Moriond" Conference. Also shows that the majority of datasets are only useful for less than one year. (But it is noticeable the files first produced seemed to be the most long lived.

27 May 2011

At last - accurate tape accounting?

So it seems we now have accurate tape accounting - CMS have looked at the new numbers generated by the new CIP code and declared that it matches their expectations.

The code accounts for data compression as it goes to tape - and estimates the free space on a tape by assuming that other data going to the same tape will compress in the same ratio. Also, as requested by ATLAS, there is accounting also for the "unreachable" data, ie data which can't be read because the tape is currently disabled, or free space which can't be used because the tape is read-only.

All the difficult stuff should now be complete: the restructuring of the internal objects to make the code more maintainable, and the nearline (aka tape) accounting. Online accounting will stay as it is for now.

11 April 2011

Summary of GridPP storage workshop at GridPP26


The full agenda is here (scroll down to "end of main meeting" :-), with presentations attached: http://www.gridpp.ac.uk/gridpp26/

Thanks again to all the sysadmins for the interesting discussions, very technical and with a high level of expertise - and I think I was the lone voice in mentioning the words "project planning" and "deliverables" and "metrics," as it should be :-)

And as you've seen, it was Dave's birthday - a glass or two was raised in The Prince George (we somehow have lots of vegetarians in the group.)

A special thanks again to our friends from Dell, not just for sponsoring GridPP26, but also for working closely with the T2s (specifically Edinburgh, Sussex, and QMUL), for being genuinely interested in the data grid we have built, and in particular for a couple of outstanding technical presentations - it is rare that you get the ever-multitasking sysadmins to close their laptops!

Oh, and as you've no doubt spotted, the graph is planar, so we conclude it does not contain a copy of K3,3 or K5. You have mathematicians writing summaries, you get planar graphs :-)

05 April 2011

GridPP26 Pictures

Last time I took pictures, I put them on the grid, and challenged people to read them.

This time I put them on the cloud: see if that works. Pictures are mostly from the dinner sponsored by Dell.


30 March 2011

Happy Birthday!!

Thank you for all the messages of congratulations on my acquirement of 31.536 M seconds of existence. After the winter break My "mother" has started again and will soon start to give me more siblings; so I am going to be getting less attention than I did 11 months ago. Plus my mother has changed how she sends my children around the world so I expect that my children will do fewer trips to other houses. However, I do still have descendants in 131 of the 705 of the rooms that ATLAS have.
Of these 131 rooms; 41 only have 1 resident, but the top four rooms have 561, 508, 472 and 192 residents!

09 March 2011

How to build a Data Grid

Went yesterday to a collaboration meeting for OOI; their oceanographic data grid is a collaboration with IC and QMUL. What is interesting is their completely different approach to building a "data grid" from how we've done it.

Building data grids was the subject of our (GridPP storage and data management) presentation at AHM last year (how to build an infrastructure that'll cope with LHC data); and an extended version will be presented at ISGC in a few weeks (more infrastructure focus, less LHC.)

While ours was essentially communication, policies, and trust, theirs is a very computersciencey approach - a message based infrastructure which promotes data to a "first class citizen" and uses formal methods (via Scribble) to implement distributed systems with "guaranteed correct behaviour." Interestingly they have about the same data rates from their sensor networks as we have in T1. Their data stream will compress to 700 MB/s.

We have thought about using formal methods before (mostly in proposals that weren't funded :-)), so it will be interesting to compare their approach to existing data grids like ESG or WLCG. Furthermore, some of their tools, like Scribble, may well find uses in some of our other projects.

(BTW, I am calling these grids "data grids," but not as much in the SRB/iRODS sense. As someone pointed out in the session, the emphasis in (any) grid processing sensor or instrument data is on the data. Computation can in principle be redone but sensor data can never be recaptured.)

15 February 2011

ATLAS Tape Store file sizes

Here is the profile of the files that are stored by ATLAS at RAL.

Minimum file size stored for both DATA and MC is 20 bytes

Maximum file size stored is:[12963033040,11943444017] or [13GB,11.9GB]

Average file size is: [1791770811,637492224] or [1.79GB,637MB]
The median filesize for [DATA,MC] are [2141069172,602938704] ([2.1GB,602MB] ) .

Number of files stored is: [282929,672707] of [DATA,MC] files for a total size of [506943923754228,428845482035182] or [507TB,428TB] in total.

[37,5687] files in [DATA,MC] are zero sized ( but we don't have to worry about them as the tape system does not copy 0 size files to tape.

However these are better than the [538,537] 20 byte files which have been migrated to tape (these are 0B sized log files which have then been "tar" and "gzip"ed before being written into Castor.)

The modal average filesizes are [26860316,0]Bytes with [286,5687] files of this size.
These are most likely failed transfers, next modal filesize with 537 entries are files with a size of 20bytes, but theses are just test files. The first genuine modal filesize jointly have 13 files and have size 19492 an 19532 Bytes.

Whereas [254040,626556] have a unique filesize (this equates to only [89.8,93.1] percent of files having a unique file size so checksum is important!!)

Could be worse though , one VO successfully stored a file that is one byte in size (the fact the header and footer on tape file and compressing the file actually increased the size of file actually stored on tape......)

07 February 2011

Get yer clouds here

At the risk of, er, promoting one of my own presentations, can I remind you to not forget to remember to join the NGS surgery this coming Wednesday, 9th, at the usual time just after the storage meeting, 10:30ish-11:30. The subject will be cloud storage in an NGI context, looking at the hows and whys and whats and whatnots, with room for discussion, too (possibly.) You can EVO in as usual if you don't have AG.

26 January 2011

Dirk get's mentioned in Nature

So at least one person other than my avatar is aware of my existence. One of my children is mentioned in the article; (even though the majority of the article is about me and ALL my children. can't be having favourites amongst them now can I??)

http://www.nature.com/news/2011/110119/full/469282a.html

Interesting point to note is only 0.02% of the total data collected by the ATLAS is represented, that's to say if I were people and ATLAS were all the people in the world; then I would represent 1.2 million people.

ATLAS have also changed now the way they send my children out. Interestingly I am now in 70/120 houses. The break down of where these rooms are is as follows:

9 rooms at BNL-OSG2.
8 rooms at CERN-PROD.
6 rooms at IN2P3-CC.
4 rooms at SLACXRD, LRZ-LMU, INFN-MILANO-ATLASC and AGLT2.
3 rooms at UKI-NORTHGRID-SHEF-HEP, UKI-LT2-QMUL, TRIUMF-LCG2,SWT2, RU-PROTVINO-IHEP, RAL-LCG2, PRAGUELCG2, NDGF-T1, MWT2, INFN-NAPOLI-ATLAS and DESY-HH.
2 rooms at WUPPERTALPROD, UNI-FREIBURG, UKI-SCOTGRID-GLASGOW, UKI-NORTHGRID-MAN-HEP, TW-FTT, TOKYO-LCG2, NIKHEF-ELPROD, NET2, MPPMU, LIP-COIMBRA, INFN-T1, GRIF-LAL, FZK-LCG2 and DESY-ZN.
1 room at AUSTRALIA-ATLAS, WISC, WEIZMANN-LCG2, UPENN, UNICPH-NBI, UKI-SOUTHGRID-RALPP, UKI-SOUTHGRID-OX-HEP, UKI-SOUTHGRID-BHAM-HEP, UKI-NORTHGRID-LIV-HEP, UKI-NORTHGRID-LANCS-HEP, UKI-LT2-RHUL, TAIWAN-LCG2, SMU, SFU-LCG2, SARA-MATRIX, RU-PNPI, RRC-KI, RO-07-NIPNE, PIC, NCG-INGRID-PT, JINR-LCG2, INFN-ROMA3, INFN-ROMA1, IN2P3-LPSC, IN2P3-LAPP, IN2P3-CPPM, IL-TAU-HEP, ILLINOISHEP, IFIC-LCG2,IFAE, HEPHY-UIBK, GRIF-LPNHE, GRIF-IRFU, GOEGRID, CSCS-LCG2, CA-SCINET-T2, CA-ALBERTA-WESTGRID-T2 and BEIJING-LCG2.


This is in total 139 of the 781 rooms at have.
The number and type of rooms are:

56 rooms of type DATADISK.
26 rooms of type LOCALGROUPDISK.
17 rooms of type SCRATCHDISK.
7 rooms of type USERDISK.
5 rooms of type PHYS-SM and PERF-JETS.
4 rooms of type PERF-FLAVTAG.
3 rooms of type PERF-MUONS, PERF-EGAMMA, MCDISK, DATATAPE and CALIBDISK.
1 room of type TZERO, PHYS-HIGGS, PHYS-BEAUTY and EOSDATADISK.


11 January 2011

Who cares about TCP anyway....

Don't worry I haven't injured myself and need a cut sterilizing, I mean window sizes!!!
So as part of my work to look at how to speed up individual transfers, I thought I would go back and look to see what the effect of changing some of our favourite TCP window settings would be. These are documented at http://fasterdata.es.net/TCP-tuning/

Our CMS instance of Castor is nice since CMS have a separate disk pool for incoming WAN transfers, outgoing WAN transfers and for pool for internal transfers between WNs and the SE. This is great feature as it means the disk servers in WanIn and WanOut will never have 100s of local connections ( a worry I have for setting TCP settings to high;) so we experimented to see what the effect of changing our TCP settings.

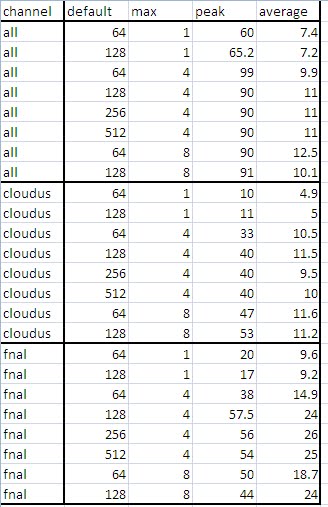
I decided to study transfers that the international as these are the large RTT transfers and most likely to benefit from tweaking. Our settings before the change were. 64kB for default and a 1MB maximum window size.
This lead to a maximum transfer rate per transfer of ~60MB/s and an average of ~7.0 MB/s.
This appears to be hardware dependent across the different generation s of kit.
We changed the settings to 128kB and 4MB. This led to an increase to ~90MB/s maximum data transfer rate per transfer and an average transfer of~11MB/s so roughly a 50% increase in performance. This might not seem a lot since we doubled and quadrupled are settings... However further analysis improves matters. changing TCP settings is only going to help with transfers where the settings at RAL were the bottleneck.
For channels where the settings at the source site are already the limiting factor then these changes would have a limited effect. However looking at transfers from FNAL to RAL for CMS we see a much greater improvement.

Before the tweak the maximum file transfer rate was ~20MB/s with an average of 6.2MB/s. However; after the TCP tweak these increased to 50MB/s and 12.9MB/s respectively.

Another set of sites where the changes dramatically helped were transfers from the US tier2s to RAL ( over the production network rather than the OPN). Before the tweaks the transfers peaked at 10Mb/s and averaged 4.9MB/s. After the tweaks, these values were 40MB/s and 10.8 MB/s respectively.

Now putting all these values into a spreadsheet and looking at other values we get:


Solid Line is Peak. Dotted line is average.
Green is total transfers.
Red is transfer from FNAL.
Blue is transfers to US T2 sites.
Tests on a pre-production system at RAL also show that the efffects on the LAN transfers for these changeas are acceptable.

14 December 2010

My Birthday Calendar...


You know that feeling of trying to get a birthday card for a relative, can you imagine the trouble I have when I have so many children! Here is my current calendar with all the days I have a relatives' birthday marked (and the number of children on each day!)

What this calendar does not take into account are early datasets and defunct reprocessing datasets which have been deleted. I would love know what makes October 3rd and June 9th so popular??? Of course some of my children are alot bigger in terms of size and files ( and importance) which is lost in this plot.

Almost Nine months old.. But still going strong.

Its been a busy year for me,
I was born nearly nine months ago now and seem to have been kept spreading.
My avatar has been remiss in reporting my exploits so I am forcing him to give you an update.
I am now only in 19 countries. These are
Australia, Austria, Canada, China, Czech republic, Denmark, France, Germany, India, Israel, Italy, Japan, Netherlands, Portugal, Spain, Russia, Taiwan, UK and the USA.
I am at 68 physical sites (134 ATLAS endpoints) .
I am in a total of 2555 datasets ( but only 857 are unique).
The top 10 popular datasets have on averaged 20.7 copies on the grid. ( Ignoring these datasets leads to an average number of copies for all off Dave's datasets is 2.7.)
In total these unique datasets now are 33.4TB ( slightly more than the original 3TB that I was to start with!!!) So an increase in ~ a factor of 11. However my modest 1779 number of files has now increased to 698749 files; (an increase factor of 392).
My next post will show my birthday calendar. ( hoping to see if there is clustering around the time before conferences...)

08 December 2010

So who's winning the transfer rate race for the Tier2 sites in the UK

Well its not really a race but I thought it would be interested to see how the rates to and from the Tier2 with RAL.
So the clear winner is ( and probably always going to be) RALPPD. This should seem obvious since they are co-located so various factors (small rtt, large bandwidth link for examples;) which would lead to a high rates. This lead to the rate plot as shown below:

Here you can see the rate has got to over 250MB/s
A close second I thought was going to be Glasgow, (they have a longer rtt and lower bandwidth pipe so you would expect them to fair worse) :


This shows that they have got to 140MB/s
Sometimes it is unfair to compare these numbers since the number of concurrent transfers on the FTS channels varies,. Glasgow actually have more concurrent transfers ( ~140MB/s with 42 concurrent transfers compare to ~250MB/s with fewer concurrent transfers.) It is because Glasgow had the most concurrent transfers that I thought it would have the highest rates:
But the peak rates I see for the sites appears to be the following (in the last month at least). If a site thinks they have seen better rates then comment on this Post!!!
( rtt time between SEs is shown in brackets after each record. Well its actually the rtt to the closest router that traceroute can resolve.)

RALPP 250 MB/s ( .2ms)
Imperial 250 MB/s (5.0ms)
Manchester 200MB/s (8.0ms)
Glasgow 140Mb/s (10.9ms)
Lancaster 100MB/s (6.4ms)
QMUL 100MB/s (5.7ms)
Birmingham 90MB/s (8.8ms)
Brunel 90MB/s (6.4ms)
Oxford 90MB/s (8.9ms)
Sheffiled 80Mb/s (9.1ms)
Liverpool 75MB/s (9.3ms)
RHUL 40MB/s (8.2ms)
Cambridge 30MB/s (10.3ms)
ECDF 20MB/s (12.9ms)
Bristol 17MB/s (4.0ms)
UCL 15MB/s (7.3ms)
Durham 12 MB/s (14.8ms)


For some sites the limiting factor seems to be the link (ie transfers are running at line speed.) For other sites the limiting factor is the number of concurrent transfers currently set in FTS. Some thing to tweak further....( Something really interesting is that the top two sites are the only dCache we have, but this could just be coincidence since they are also the shortest and close to second shortest rtt times of any site.

ATLAS have also started their sonar T2-T2 mesh of testing inter cloud T2 transfers. this made me think of the work I had done (but not reported) about work I had done in looking in splitting STAR-T2 channels at RAL into a slow medium and fast channels. the rough split is western European sites in fast channel, north America in the medium channel and south America/Asia-pacific in slow channel ( going from rtt time) . This would be an initial split and then some tweaking if some sites were slower than their rtt would suggest.
Interesting to see if ATLAS list of slow transfers for UK sites match mine.
my list of slow sites would be:

Australia-ATLAS
BEIJING-LCG2
CBPF
EELA-UTFSM
LCG_KNU
MA-01-CNRST
NCP-LCG2
SDU-LCG2
TOKYO-LCG2
UNIANDES
TW-FTT
TR-10-ULAKBIM
INDIACMS-TIFR


Medium sites ( North America)would be:
Canadian
CA-ALBERTA-WESTGRID-T2
CA-SCINET-T2
CA-VICTORIA-WESTGRID-T2
SFU-LCG2
VICTORIA-LCG2

American
UST3
BUATLAS
UMICH
IUT
UTA
OU
UIUC
UCTP
STU
UCT2
SMU
AGLT2
WIS
UMFS
SWT2UTA
SWT2CPN

Plus I am working with Glasgow to see how much of their 6Gbps can be used; but more on that in my next post.

03 November 2010

Confederated conference confusion

Summaries of the data management sessions at last week's OGF, as well as more CHEP discussion, have appeared in the minutes of this week's storage meeting. Meanwhile, there is a HEPiX meeting this week, which will (probably) be discussed at the storage meeting next week - particularly if we can find someone who went to it. Share and Enjoy.

24 October 2010

A computing banquet

Delayed post from Thursday....
So another day, another 100 talks, followed by another 100 food courses.

Just to provoke a suitable tirade from Sam, I will describe that morning's SSD plenary as an "informative and thorough summary on the unquestionable advantages of SSDs" (not really). More interesting was a talk from David South on long term data preservation for experiments. A very worthwhile idea I think, and I hope it can be supported.
In parallel talks, there was an update on Hammercloud developments - now available for LHCb, CMS as well ATLAS and apparanty in the future other VOs will be able to "plugin". Also coming in the future are more advanced/configurable statistics.
Andreas Peters outlined the cern "disk pool project" EOS, and, as mentioned by Sam, the obvious questions followed from Brian B and others, "why yet another filsystem/ storage manager? Are dCache. HDFS etc.etc. etc not worth adapting..." But to look at the positive side (as they are certainly going to carry on with this anyway) if something good develops then it maybe something worth T1s or T2s trying out.
In the same session there was another tool presented that we might use, a flexible benchmark that allows you to trace any application and then "play it back": copying the disk calls.Potentially very useful for testing out new kit - and, though it hasn't yet been packaged for general consumption, we'll defiantely be following up with the developer for a preview.

Friday was the stream leaders summaries, which you don't need since you have had ours ;-).
Overall I've been very impressed both with the organisation of the conference and of the quality of the talks...

And, as my temple visits should have placated the travel gods to guide me home through typhoons, strikes and whatever else is out there; we should be back to provide a more digested summary in next wednesdays storage meeting.

20 October 2010

CHEP: or, how I learned to stop worrying and love the rain.

So, day three of CHEP was a half day, so not so much to report as Wahid did yesterday.

The plenaries were not directly interesting from a storage perspective, but I should ebtion them for other qualities.
First, Kate Keahey told us all why clouds (and public clouds, federated clouds - "sky computing") were awesome. I guess I'm just a cynic, as I still don't see how they're significantly better than Condor pools (plus flocking, plus VM universe). Also, the data flow problem is decidedly unsolved for analysis-class jobs in this context.


Secondly, Lucas Taylor impressed on us how important it was to talk to the media (and, more importantly by far, the public). Apparently, the most significant source of hits on CERN webpages is Twitter! Considering also that the LHC is only 1/3 as popular as Barack Obama on YouTube, it does seem that the right approach can really bring in public interest, and this can only be a good thing.


Finally, Peter Malzcher told us about the FAIR project, which is to be the next big accelerator at GSI. Honestly, it looks awesome, but the 6MW cooling solution for the cluster looks terrifying.


Since I was presenting today, I only have notes from the session I was scheduled for.

The first two talks, both on virtualisation, confirmed that io can be an issue for many-VM hosts. The solution of the day appears to be iSCSI.
Then some dangerous radical told everyone to throw their shoes in the machinery that MLC flash isn't all it's cracked up to be in SSDs.
More upsets followed when Yves Kemp showed that pNFS/NFS4.1 is much better than dCap in almost all possible cases. It is, however, possible that dCap's problem is simply too much readahead.
Finally, Dirk Duellmann gave us an update from CERN storage. Essentially, they're pretty stable at the front-end, growing storage at 15PB/y. Additionally, they're trialling EOS for disk pool filesystems. EOS, as Jeff Templon got Dirk to admit under cross-examination, is basically Hadoop over xrootd protocol, with a better namespace.
Despite agreeing at Amsterdam that reinventing the wheel in private projects was Bad... (CERN could have chosen to patch Hadoop, or even Ceph, instead).

Tch.

CHEPping part 2

Having got my talk out of the way (more on that later), I am now free to blog my view on activities so far here in Taiwan. I will avoid telling you about the driving rain, puppet shows and million-mini-course dinners, sticking instead to the hard storage facts.
My highlight/snippets on Monday/Tuesday activities:
- Lots on many core - but the valid question was asked, can IO keep up with this?
- Partick told us the plans (as they are now) for Data management middleware in EMI. Storm is in the plans (though was somewhat absent from the session to provide an update on their status.)
- Oliver told us the roadmap for DPM:(immediate news is that DPM 1.8.0 is in certification including a 3rd party rfcp to allow it to be used for draining.)
- Ricardo gave a nice talk on the DPM work on NFS4.1 which has reached the stage of a prototype.
For the slides on the later talks see this session:
http://117.103.105.177/MaKaC/sessionDisplay.py?sessionId=33&slotId=0&confId=3#2010-10-19

- My talk went OK with many questions, including those (interested in) doing similar benchmarking work. Hopefully we can get some common ideas towards providing something useful for sites to test and tune.
- Unfortunately I was talking at the same time as Illija's talk on the ATLAS root improvements which among other things outline that some of the further improvements in ROOT 5.26 would not be available in the current ATLAS reprocessing due to some other bugs which, thanks to connections made during the talk, may get fixed. Also up at the same time (!
) was Philippe Canal's talk with more detail on the ROOT changes as well as CMS's experiences in implementing them (http://117.103.105.177/MaKaC/contributionDisplay.py?contribId=150&sessionId=46&confId=3)

Other news - we had a very productive meeting with the DPM team, which should see us soon getting hold of the prerelease NFS4.1 interface for testing (around the next month) and also (probably before that) we'll be testing the "3rd party rfcp" mentioned above to tune it for fastest possible drains (yeah!) . We also talked about creating a central repository to collect together any DPM related nagios probes that people are using (before consolodating / adding new ones)

Packed days (so many sessions at once that even with Sam and I covering different sessions we are still missing half the stuff) - and we are only half way through! So standby for more info, if I don't get lost in the electronics markets or washed away by a typhoon.

18 October 2010

CHEP 2010: Episode 4: A New Hope

The story so far:

The evil Empire of CERN has succeeded in paralyzing the world's data networks by distributing vast quantities of 'event data' from their Death Star in Geneva.

However, at this very moment, a band of resistance fighters are congregating on the forest moon island of Taiwan to lead the fight back...


Ahem. So, Wahid and I are currently in Taipei for CHEP2010. Despite the jetlag encouraging me to write paragraphs like the above, we're seeing lots of interesting things.
Tellingly, the inaugural speech was given by the Vice President of Taiwan, and he mentioned how important Science was to Taiwanese success. Unlike France, I suspect the UK would find it hard to get Nick Clegg to turn up in similar circumstances.
Back to physics, where Ian Bird, and Roger Jones sequentially told us how successful we'd all been over the year, and Craig Lee told us how awesome cloud computing will be when it is public. Just like the Grid (and Condor clusters) before it, eh?
Finally, we had a discussion of many-core scaling for LHC VOs by Sverre Jarp. This is an area of significance in data provision, and the challenge of scaling io is something we're still looking at how best to address.

Of the parallel talks I attended, the most interesting was the CERNVMFS talk - it's still impressive how well it works.
Other interesting things: talks on EMI release processes (they have QA metrics!), posters on FTS over scp, Amazon ECC for CMS (too expensive), L-Grid webportal, and the ATLAS consistency service.

More from Wahid tomorrow.

14 September 2010

Aran Fawddwy

Welcome to Wales, to Cardiff actually, but if there are (real) mountains in Cardiff then I haven't seen them yet. The environment is certainly impressive, in Cardiff's city hall. As science conferences go, we're not used to such impressive surroundings.

Currently in the data management session where we have just heard from the UKQCD collaboration. It is interesting that their data grid is the stuff that we (GridPP) run, and the stuff the other guys run - ILDG is a collaboration of five countries, and they don't all run the same thing, but as long as they interoperate. As usual, GridFTP is the workhorse moving data back and forth, but even then data volumes are such that "truckftp" is sometimes quicker.

Oh, if you're around, don't forget to stop by the GridPP/NGS stand and say hi.

31 August 2010

Taming XFS on SL5

Sites (including Liverpool) running DPM on pool nodes running SL5 with XFS file systems have been experiencing very high (up to multiple 100s Load Average and close to 100% CPU IO WAIT) load when a number of analysis jobs were accessing data simultaneously with rfcp.

The exact same hardware and file systems under SL4 had shown no excessive load, and the SL5 systems had shown no problems under system stress testing/burn-in. Also, the problem was occurring from a relatively small number of parallel transfers (about 5 or more on Liverpool's systems were enough to show an increased load compared to SL4).

Some admins have found that using ext4 at least alleviates the problem although apparently it still occurs under enough load. Migrating production servers with TBs of live data from one FS to another isn't hard but would be a drawn out process for many sites.

The fundamental problem for either FS appears to be IOPS overload on the arrays rather than sheer throughput, although why this is occurring so much under SL5 and not under SL4 is still a bit of a mystery. There may be changes in controller drivers, XFS, kernel block access, DPM access patterns or default parameters.

When faced with an IOPS overload (that's resulting well below the theoretical throughput of the array) one solution is to make each IO operation access more bits from the storage device so that you need to make fewer but larger read requests.

This leads to the actual fix (we have been doing this by default on our 3ware systems but we just assumed the Areca defaults were already optimal).
blockdev --setra 16384 /dev/$RAIDDEVICE

This sets the block device read ahead to (16384/2)kB (8MB). We have previously (on 3ware controllers) had to do this to get the full throughput from the controller. The default on our Areca 1280MLs is 128 (64kB read ahead). So when lots of parallel transfers are occurring our arrays have been thrashing spindles pulling off small 64kB chunks from each different file. These files are usually many hundreds or thousands of MB where reading MBs at a time would be much more efficient.

The mystery for us is more why the SL4 systems *don't* overload rather than why SL5 does, as the SL4 systems use the exact same default values.

Here is a ganglia plot of our pool nodes under about as much load as we can put on them at the moment. Note that previously our SL5 nodes would have LAs in the 10s or 100s under this load or less.

http://hep.ph.liv.ac.uk/~jbland/xfs-fix.html

Any time the systems go above 1LA now is when they're also having data written at a high rate. On that note we also hadn't configured our Arecas to have their block max sector size aligned with the RAID chunk size with

echo "64" > /sys/block/$RAIDDEVICE/queue/max_sectors_kb

although we don't think this had any bearing on the overloading and might not be necessary.
 
We expect the tweak to also work for systems running ext4 as the underlying hardware access would still be a bottle neck, just at a different level of access.

Note that this 'fix' doesn't fix the even more fundamental problem as pointed out by others that DPM doesn't rate limit connections to pool nodes. All this fix does is (hopefully) push the current limit where overload occurs above the point that our WNs can pull data.

There is also a concern that using a big read ahead may affect small random (RFIO) access although the sites can tune this parameter very quickly to get optimum access. 8MB is slightly arbitrary but 64kB is certainly too small for any sensible access I can envisage to LHC data. Most access is via full file copy (rfcp) reads at the moment.